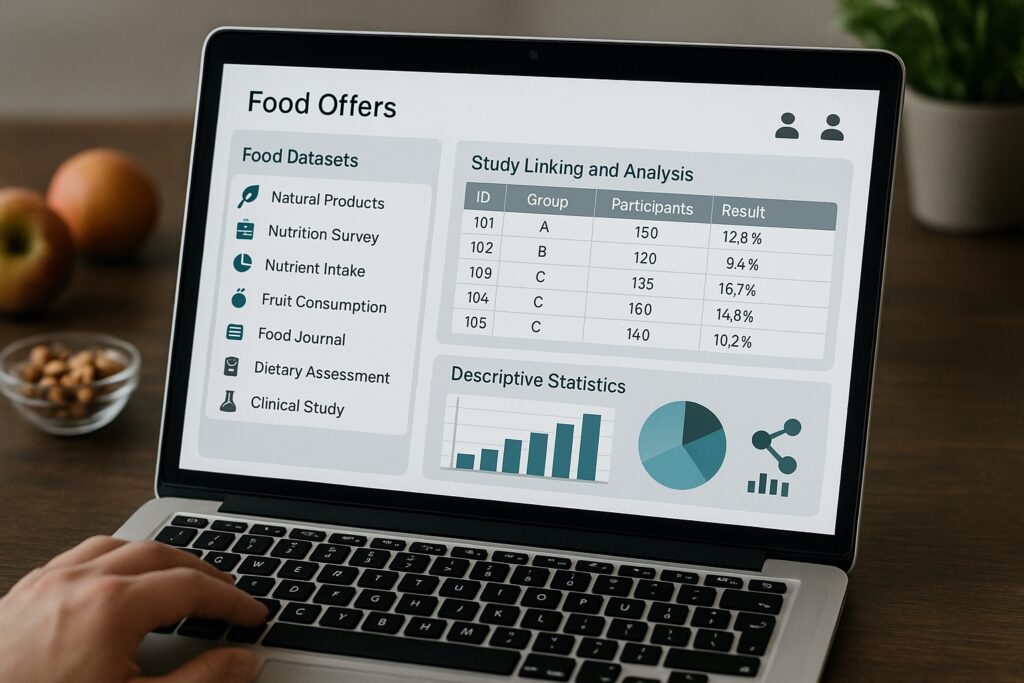
transmartproject.org food offers open tools for shared food and nutrition data. Researchers use the platform to store data, link study results, and run basic analyses. The site hosts phenotypes, assays, and clinical variables. The guide explains how teams prepare data, import files, run visual queries, and share results with collaborators.
Key Takeaways
- transmartproject.org food is an open-source platform that links diet data with clinical and molecular results, enhancing food and nutrition research.
- Researchers prepare and standardize food and nutrition datasets by cleaning data, mapping dietary variables to controlled vocabularies, and validating files before importing into the platform.
- Users run cohort queries, perform statistical analyses, and visualize results with built-in tools like boxplots and heatmaps to explore associations between diet and health outcomes.
- The platform supports collaboration by allowing controlled data sharing, version tracking, and attaching analysis notes to ensure transparency and data governance.
- Researchers export data to external tools for advanced modeling and reuse shared datasets for meta-analyses, promoting discoverability and reproducibility in food research.
- Documenting every step, including metadata and scripts, ensures a reproducible workflow and facilitates peer review and future study reuse.
What TranSMART Is And Why It Matters For Food Data
TranSMART is an open-source data platform. It stores clinical and molecular data. It supports cohort queries and integrated analyses. Food researchers use transmartproject.org food because it links diet data to lab results. The platform handles phenotypes, survey data, metabolomics, and microbiome profiles. It lets teams compare groups and find associations.
The project provides a standardized data model. The model maps variables to common terms. Researchers map food intake fields to these terms. This mapping improves data search and reuse. It also reduces errors when teams merge datasets.
TranSMART offers user tools and APIs. Scientists access a web interface for queries. Developers use APIs to load and extract data. The platform integrates open analysis tools and R scripts. Teams can run statistical tests and export tables.
The site supports collaboration. Teams share cohorts and results inside the platform. They control access with user roles. This control keeps sensitive food study data secure. It also helps teams track versions and provenance.
Preparing, Formatting, And Importing Food And Nutrition Datasets
Researchers prepare files before they import to transmartproject.org food. They clean raw data and remove duplicates. They standardize column names and use clear units. They convert dates to ISO format. They assign consistent subject IDs across files.
Researchers format subject and assay tables to match the tranSMART schema. They create a subject phenotype file with study IDs, age, sex, and diet fields. They create assay files for metabolomics or microbiome with sample IDs and values. They keep one header row and plain text or CSV format.
Researchers map dietary variables to controlled vocabularies. They use common food codes or simple descriptors. They avoid free-text answers for intake where possible. They create lookup tables for food frequency items. They convert portion sizes to grams or standard units.
Researchers validate files before upload. They run small scripts to check missing values and inconsistent IDs. They run a sample import on a test instance. They correct mapping errors and re-run validation.
Researchers import data using the tranSMART ETL or APIs. They load a subject file first. They then load assay files and link sample IDs to subjects. They watch the import logs for errors. They fix row or format errors and re-import affected files.
Researchers document each step. They store import scripts, mapping tables, and version notes. They add metadata about collection methods and diet assessment tools. This documentation helps future reuse and peer review.
Analyzing, Visualizing, And Sharing Food Research Findings With TranSMART
Researchers run cohort queries on transmartproject.org food. They filter subjects by diet patterns, biomarkers, or outcomes. They build phenotype trees to select groups. They run statistical tests to compare means and proportions.
Researchers visualize results inside the platform. They create boxplots, heatmaps, and scatterplots. They inspect metabolite trends against intake variables. They use volcano plots for differential analyses. They export plots for reports and publications.
Researchers connect external tools for advanced analysis. They export cohorts to R or Python for modeling. They run linear models, mixed models, or machine learning. They bring back processed results and store them in the platform.
Researchers share findings with collaborators on the site. They grant read or write permissions to projects. They attach analysis notes and script files to study records. They record provenance so teams can trace each result back to raw data.
Researchers follow data governance and privacy rules. They remove direct identifiers and apply access controls. They use synthetic or summary datasets for public sharing. They publish metadata and aggregated tables to boost discovery.
Researchers reuse shared datasets for meta-analysis. They merge cohorts across studies and run pooled tests. They compare diet effects across populations. They write methods that reference transmartproject.org food and include dataset accession IDs for transparency.
Researchers keep a reproducible workflow. They save scripts, parameter settings, and plot versions. They include a README that explains each step. This practice ensures that team members and reviewers can follow the work.